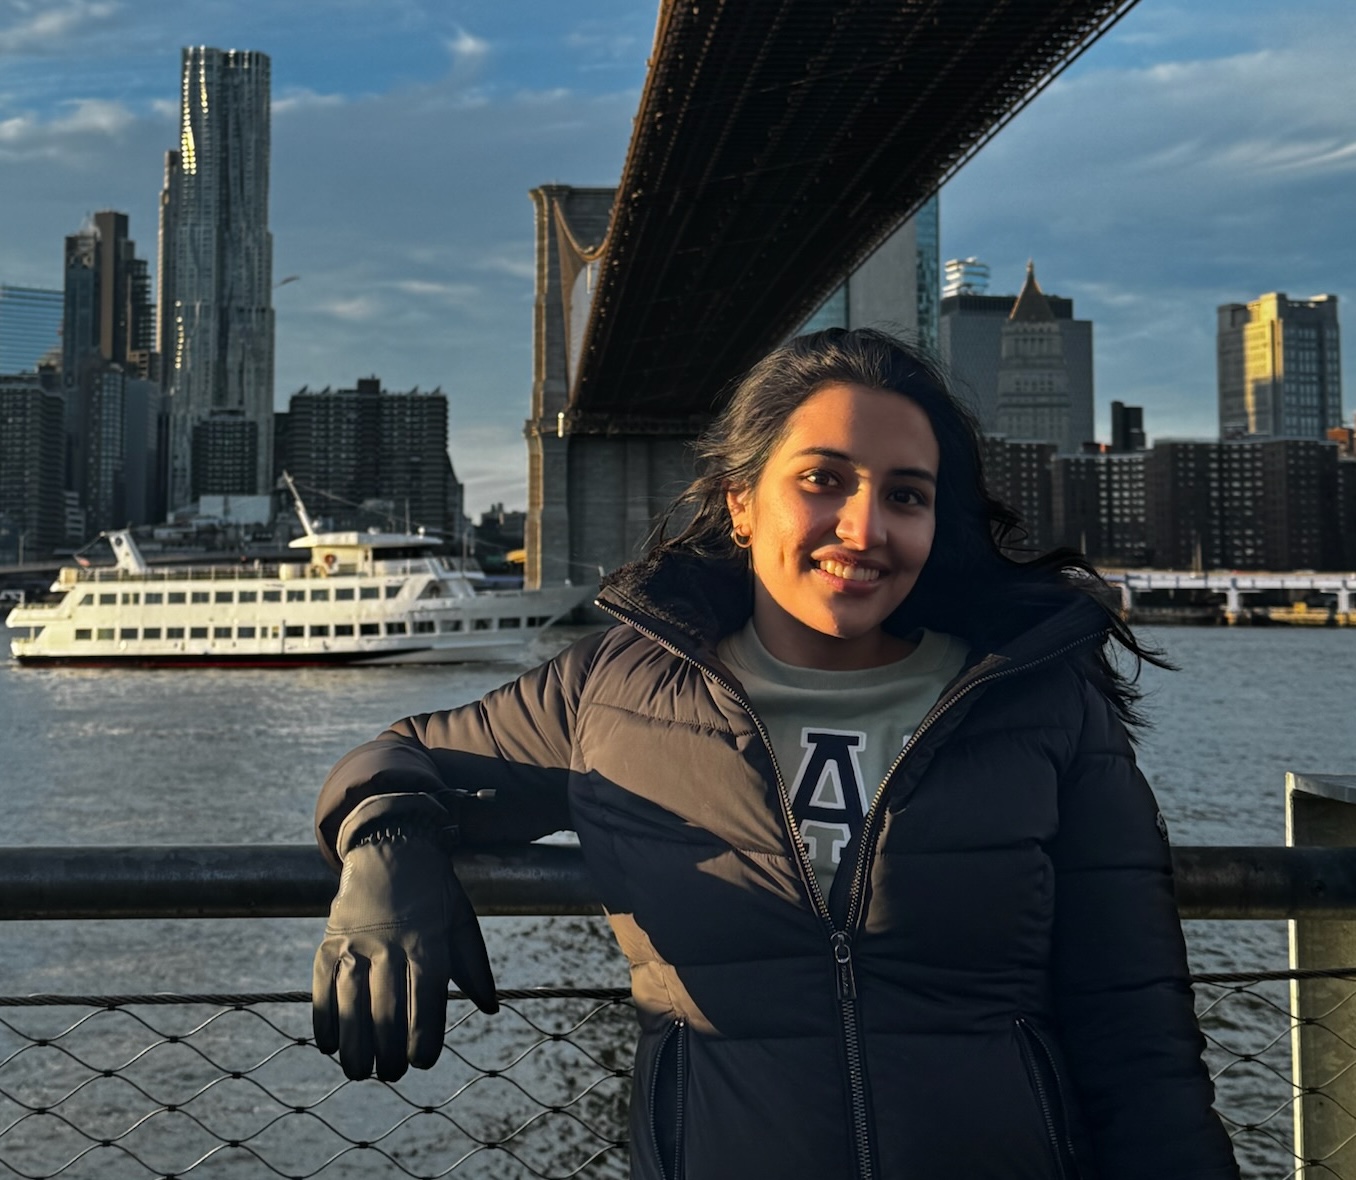
Hello, I am
01
I am a master's student in Computer Science at the University of Pennsylvania, where I work at the intersection of machine learning research and software engineering. Three years of writing production code at Lexmark | Xerox taught me that good systems and good models share the same foundation: they need to work for real people in real conditions. At Penn, I am learning how to bring research depth to the systems I build, and engineering discipline to the research I do.
Outside of my academic and technical work, I enjoy reading, watching films, and exploring music. I often find myself reflecting on a book I recently finished, a film that stayed with me, or a song I have been listening to on repeat. These are interests I genuinely enjoy engaging with in my free time.
I love building things that sit at the intersection of intelligent systems and practical impact, whether that means fine-tuning language models or designing a full-stack application from scratch.
Open to Software Engineering, Data Science, and Machine Learning internship opportunities for Summer 2026. Always excited about meaningful collaborations and open-source contributions. If something here resonates, let's talk.
02
Master of Science in Engineering, Computer and Information Science
Philadelphia, PA
Bachelor of Technology (Hons.) in Information Technology
Kolkata, India
03
Distributed Systems
Built a fault-tolerant distributed cloud platform in C++ featuring webmail and file storage across 5 replicated backend servers, supporting file uploads of 800MB+. Implemented primary-based replication across 10 tablets (each on 3 replicas), write-ahead logging, and checkpointing with two-path crash recovery ensuring zero data loss across node failures. Includes a master coordinator with automatic primary election within one 250ms heartbeat cycle, a frontend load balancer, and an admin console for live fault injection and recovery testing.
Read the full write-up →Machine Learning Research
Studied how knowledge distillation reshapes failure modes in Retrieval-Augmented Generation systems. Built a controlled RAG pipeline on the SciFact biomedical benchmark, evaluated six chunking strategies, and distilled a 1B-parameter student from a 70B teacher using LoRA fine-tuning. Categorized failures using the Seven Failure Points taxonomy across 338 validation claims. While accuracy dropped 14.2 points, the student hallucinated roughly 30x more often (0.3% → 8.9%) and amplified the teacher's label bias, demonstrating that aggregate accuracy hides critical deployment risks in distilled RAG.
Machine Learning Research
Built a generative simulation framework to tackle extreme class imbalance in social data. The system synthesizes realistic responses across 25 distinct personas, enabling model training on heavily skewed datasets. I benchmarked classical and neural approaches before fine-tuning a language model with LoRA, achieving strong gains over zero-shot baselines.
Deep Learning Research
Designed a cross-modal retrieval architecture that aligns visual and textual representations through bidirectional co-attention. By fusing frozen ViT and BERT features before pooling, the model captures fine-grained correspondences between image regions and text tokens, outperforming standard contrastive approaches on Flickr30k retrieval benchmarks.
Full Stack Development
Created an end-to-end analytics platform that aggregates and visualizes hiring trends across a large-scale job market dataset. The system features a carefully normalized database schema, RESTful APIs, and an interactive frontend for exploring hiring hotspots, with query optimizations that brought analytics response times well under a second.
04
Software Engineer · Kolkata, India · Jul 2022 - Jul 2025
Over three years at Lexmark | Xerox, I worked across the enterprise stack (Azure, .NET, Dynamics 365, Dataverse), building event-driven systems, distributed ingestion pipelines, and modernizing legacy infrastructure. Most of it happened in a SAFe Agile environment, in close collaboration with product, QA, and architecture.
Associate Software Engineer Intern · Kolkata, India · Sep 2021 - May 2022
As an intern on the financial technologies team, I worked on configuration management and tooling for security brokerage platforms, building Java applications alongside teams that supported live client systems. The role taught me how to ship safely against production constraints and communicate technical changes to non-engineering stakeholders.
05
My current research investigates how large language models behave when they encounter errors in multi-step agentic pipelines. I am building trajectory-level datasets by introducing controlled perturbations into intermediate agent steps, studying how models detect and recover from mistakes, and exploring whether fine-tuning can improve their self-correction capabilities in complex software engineering tasks.
This work explores whether large language models can improve their own reasoning without relying on an external teacher. Recent findings show that off-policy methods like SFT and off-policy distillation often lead to forgetting, while on-policy approaches better preserve existing capabilities. Building on the observation that even incorrect chain-of-thought traces from a distributionally closer source can boost reasoning performance, we study whether a model's own synthetic outputs, both correct and incorrect, are sufficient to strengthen its reasoning through self-distillation alone, removing the need for a separate teacher model entirely.
A research paper on applying pattern recognition techniques to classify music genres from audio signals. Currently being prepared for submission to BVICAM's International Journal of Information Technology.
06